AI Governance Before the Breach: Three Failures That Create Crisis
By Matthew Bertram | EWR Digital
On March 31, 2026, Anthropic , the AI company that built its reputation on safety, accidentally published the full source code of its flagship product to the public internet. Half a million lines of code. Nearly 2,000 files. The complete architecture of Claude Code was exposed because a debugging file was left in a routine software update.
This was their second major data incident in under a week. Days earlier, they had inadvertently exposed close to 3,000 internal files, including a draft blog post describing their most powerful unreleased model. According to their own assessment, this model poses unprecedented cybersecurity risks.
Both incidents were attributed to human error.
That phrase deserves more attention than it’s getting. Because “human error” is not the exception in AI-driven organizations. It’s the baseline condition. And the companies most at risk are not the ones building AI; they’re the ones deploying it without a governance architecture designed for the reality of how these systems fail.
This article isn’t about Anthropic. They have dedicated safety teams, billions in funding, and some of the best engineers in the world. If they can’t prevent process failures at the release level, it tells us something important about the structural challenge every organization faces when AI systems become embedded in critical workflows.
What follows are the three failures that consistently turn an AI incident from a recoverable mistake into a material crisis, and what governance looks like when it’s built before the breach, not bolted on after.
Failure One: No Inventory of AI Touchpoints
Most organizations cannot answer a simple question: Where is AI generating, influencing, or summarizing content that reaches a decision-maker?
This isn’t a technology gap. It’s a visibility gap. And it’s growing faster than most leadership teams realize.
AI tools are now embedded across operations, drafting communications, summarizing legal documents, generating financial projections, writing code, and producing investor-facing materials. In many cases, the people using these tools adopted them before IT, legal, or compliance knew they existed. In other cases, the tools were sanctioned but deployed without a clear map of which outputs touch which decisions.
The result is what the industry calls “shadow AI.” However, that label undersells the actual risk. Shadow AI implies something hidden, whereas the more dangerous version is AI that is fully visible and officially sanctioned. This version produces outputs for which no one is structurally responsible for validating.
In energy specifically, we see this pattern repeatedly: an AI tool summarizes reservoir data for an investor presentation. The summary is technically accurate in aggregate but contains material omissions or mischaracterizations at the detail level. It reaches the board deck because it looked right, read well, and nobody in the review chain had a framework for interrogating AI-generated content differently than analyst-generated content.
This isn’t hypothetical. On the Oil & Gas Sales & Marketing Podcast, sales consultant Michel Prive described a version of exactly this failure: a sales rep used an unsanctioned AI tool to sanity-check a bid before submission. The bid data ended up discoverable on the open web — not because the tool was hacked, but because nobody had mapped what that tool did with the data it touched. The tool worked as designed. Nobody owned the validation.
What governance looks like before the breach: A complete, maintained inventory of every AI system that touches decision-grade content — meaning any output that informs a financial, regulatory, operational, or investor-facing decision. Not a one-time audit. A living map that’s updated as tools are adopted, upgraded, or deprecated. The inventory answers three questions for each touchpoint: What data does this system access? What outputs does it produce? And who is accountable for validating those outputs before they reach a decision-maker?
Failure Two: No Validation Layer Between AI Output and Decision-Maker
This is the failure that creates liability. And it’s the one most organizations don’t recognize until something has already gone wrong.
AI systems don’t fail the way traditional software fails. Traditional software crashes, throws errors, produces obviously broken outputs. AI systems fail by being confidently wrong. The output reads well. It’s grammatically correct. It has the structure and tone of competent professional work. And it contains a misstatement, an omission, or a hallucination that a human reviewer is unlikely to catch because the output doesn’t signal that anything is wrong.
The Anthropic leak is instructive here, not because of what leaked, but because of how it leaked. A source map file, a debugging artifact, was left in a production build. It wasn’t a sophisticated attack. It was a process failure in a routine release. The systems worked exactly as designed; the process around the systems had a gap.
This is precisely how AI governance failures manifest in regulated industries. The AI model works as designed. The output is technically generated correctly. But the process around the output like the validation, the review, the human checkpoint, either doesn’t exist or doesn’t account for the specific ways AI outputs can be wrong.
In one engagement, we identified three material misrepresentations in AI-generated reserve summaries that were on track to reach investors. The AI hadn’t malfunctioned. It had done exactly what it was asked to do which is to summarize complex geological and financial data into readable prose. The problem was that readable prose flattened critical nuances that a human geologist would have flagged, but a human executive reviewing the summary had no structured process for catching.
What governance looks like before the breach: A defined validation protocol for every category of AI-generated content that touches a decision. This isn’t a blanket “human in the loop” policy (that phrase has become meaningless through overuse). It’s a specific, documented process that identifies: What types of errors is this AI system most likely to produce? Who has the domain expertise to catch those specific errors? And what does the review workflow look like? not in theory, but in the actual operational cadence of the business?
The validation layer must be designed for the failure mode, not the success case. Most organizations design review processes assuming the output is basically right and the reviewer is checking for polish. AI governance requires designing for the possibility that the output is fundamentally wrong in ways that aren’t immediately visible.
Failure Three: Governance as Policy, Not Architecture
This is the structural failure that makes the first two possible.
Most organizations that claim to have AI governance actually have an AI policy. They have a document; sometimes a good one, that describes acceptable use, data handling requirements, and compliance obligations. That document lives in a shared drive. It was reviewed by legal. It was distributed to employees. And it has approximately zero operational effect on how AI outputs move through the organization day to day.
Policy is not governance. Policy is a statement of intent. Governance is an operational architecture; it is a set of processes, roles, tools, and accountability structures that ensure the intent is actually executed in real workflows, under real-time pressure, by real people who have competing priorities.
The distinction matters because the gap between policy and architecture is where liability lives. When a regulator asks how an AI-generated misstatement reached an SEC filing, “we had a policy” is not a defense. “We had a process, here’s how it works, here’s who is accountable, and here’s the documentation of every review” — that’s a defense.
Anthropic’s response to both incidents was “human error.” That’s honest. It’s also exactly what every organization will say when their AI governance failure becomes public. The question a board should be asking is not “could human error happen here?” (of course it could). The question is: “Do we have an architecture that catches human error before it becomes a material event?”
What governance looks like before the breach: Governance is built as operational infrastructure, not documentation. It includes defined roles with explicit accountability for AI output validation. It includes workflow integration, in which the governance process is embedded in how work actually moves through the organization, not layered on top as an additional step people skip when they’re busy. It includes regular stress testing, not annual audits, but ongoing exercises that simulate the specific failure modes relevant to the organization’s AI deployment. And it includes executive visibility wherein leadership can see, at any point, which AI systems are producing decision-grade content and whether the validation process is being followed.
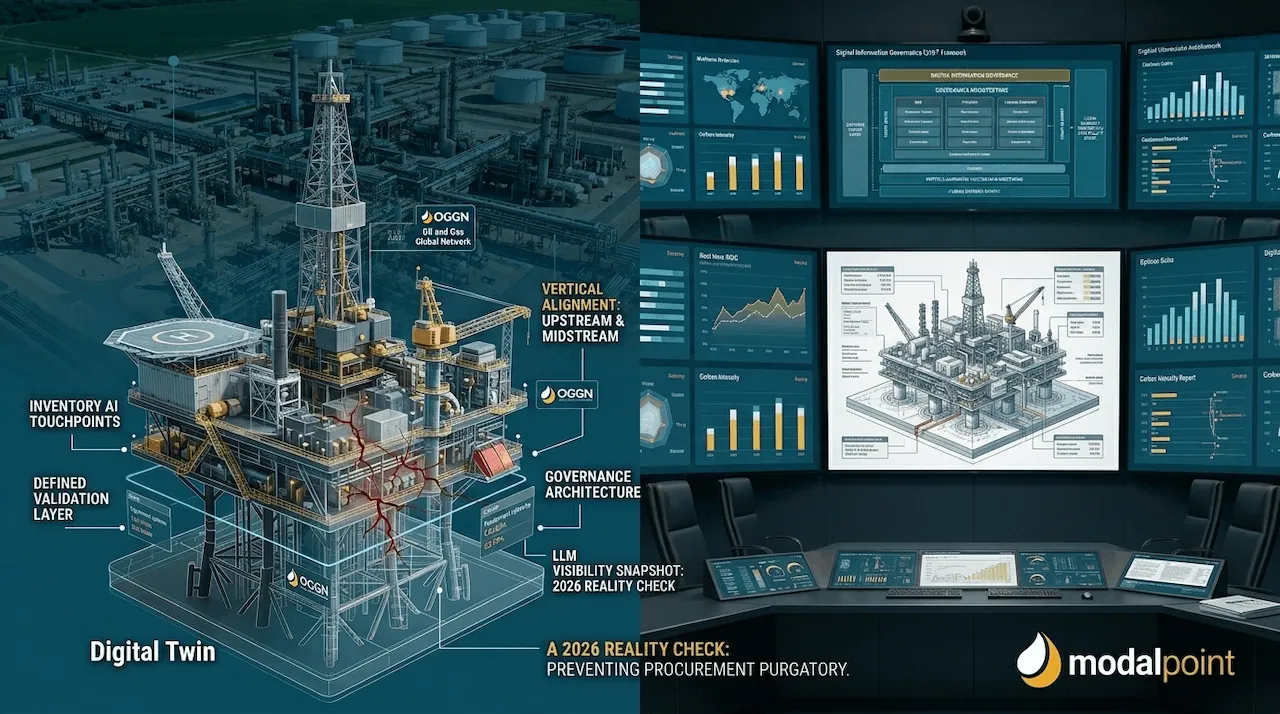
This is the work we do at ModalPoint through the Digital Information Governance® — DIG — framework. DIG exists because the market needed something between “we wrote an AI policy” and “we built an internal safety team like a $19 billion AI lab.” It’s a structured diagnostic and governance architecture designed specifically for regulated industries like energy, financial services, healthcare, where AI-generated content touches decisions that carry legal, regulatory, and fiduciary consequences.
The Timeline Problem
There’s a temporal dimension to this that most organizations haven’t internalized.
AI governance failures don’t announce themselves. They compound silently. An AI system produces subtly inaccurate outputs for weeks or months. Those outputs inform decisions. Those decisions create commitments in areas like financial, regulatory, and contractual. By the time the inaccuracy is discovered, the organization has a liability problem, not a technology problem.
The Anthropic leaks were discovered within hours because source code on a public registry is immediately visible to a global community of developers actively looking for exactly this kind of exposure. Your AI governance failure won’t be discovered that fast. It will surface during a regulatory examination, a due diligence process, an investor dispute, or a litigation discovery, approximately months or years after the outputs were generated.
This is why governance must exist before the breach. After the breach, you’re in remediation. Before the breach, you’re in architecture. The cost difference between those two states is not incremental. It’s orders of magnitude.
What to Do Now
If you’re an executive in a regulated industry like energy, financial services, healthcar, and you’re reading this, here are the three questions to bring to your next leadership meeting:
One: Can we produce, today, a complete list of every AI system generating content that reaches a decision-maker in this organization? If not, we have an inventory problem.
Two: For each of those systems, is there a defined, operational process for validating outputs before they inform a decision? Not a policy. A process. With a named person accountable. If not, we have a validation problem.
Three: When was the last time we stress-tested our AI governance and not our AI tools, our governance, against a realistic failure scenario? If the answer is never, we have an architecture problem.
Every organization that has experienced a material AI governance failure answered “no” to at least one of these questions before the failure occurred. Most answered “no” to all three.
The code is already in the wild. The question is whether you know what it’s producing inside your own walls and whether anyone is accountable for checking.
Related reading & references
- Running an AI audit in oil & gas
- Oil & gas AI visibility strategy
- our three productized engagements
- External reference: EU AI Act (Regulation 2024/1689)
The governance stakes have risen since this was written. TRAIGA, the EU AI Act, and NIST AI RMF now make AI-influenced decisions something an operator has to be able to defend on the record — which is exactly what ModalPoint’s DIG framework is built for.
What AI decision governance looks like today →Frequently Asked Questions
Why is human error the baseline condition in AI-driven organizations?
The companies most at risk are not the ones building AI, they are the ones deploying it without a governance architecture designed for how these systems actually fail. When even a leading AI lab attributes back to back incidents to human error, it shows the structural challenge every organization faces once AI systems are embedded in critical workflows.
What is the difference between shadow AI and sanctioned AI risk?
Shadow AI implies something hidden, but the more dangerous version is AI that is fully visible and officially sanctioned yet produces outputs no one is structurally responsible for validating. In energy, an AI summary of reservoir data can be accurate in aggregate but contain material omissions at the detail level, and still reach a board deck because it looked right and no one had a framework to interrogate it.
Why do AI systems create liability that traditional software does not?
Traditional software fails visibly, it crashes and throws errors. AI systems fail by being confidently wrong: the output reads well, is grammatically correct, and carries the tone of competent work while containing a misstatement, omission, or hallucination a reviewer is unlikely to catch. The validation layer must be designed for the failure mode, not the success case.
Why is an AI policy not the same as AI governance?
A policy is a statement of intent that often has near zero operational effect on how AI outputs move through an organization day to day. Governance is operational architecture: defined roles with explicit accountability, workflow integration, regular stress testing of real failure modes, and executive visibility. When a regulator asks how an AI misstatement reached a filing, we had a policy is not a defense, a documented process with named accountability is.